

Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Your Next Vendor Benchmark Should Look Like a QA Harness, Not a Chat Demo
If you work in software and QA, you already know the gold standard for evaluating a system: same inputs, same seed, every change versioned, every run replayable. You would never certify a release on a demo someone narrated to you. So why do enterprises buy AI agents based on chat quality — cherry-picked prompts, no diff, no replay?
That question is being answered in public right now. Firmulate runs AI models as complete companies — real money mechanics, real crises, real temptations to cheat — and measures management quality, not chat quality. Every business day is versioned, and every decision is a commit you can replay. It is, essentially, a continuous integration pipeline for management judgment.
The Experiment
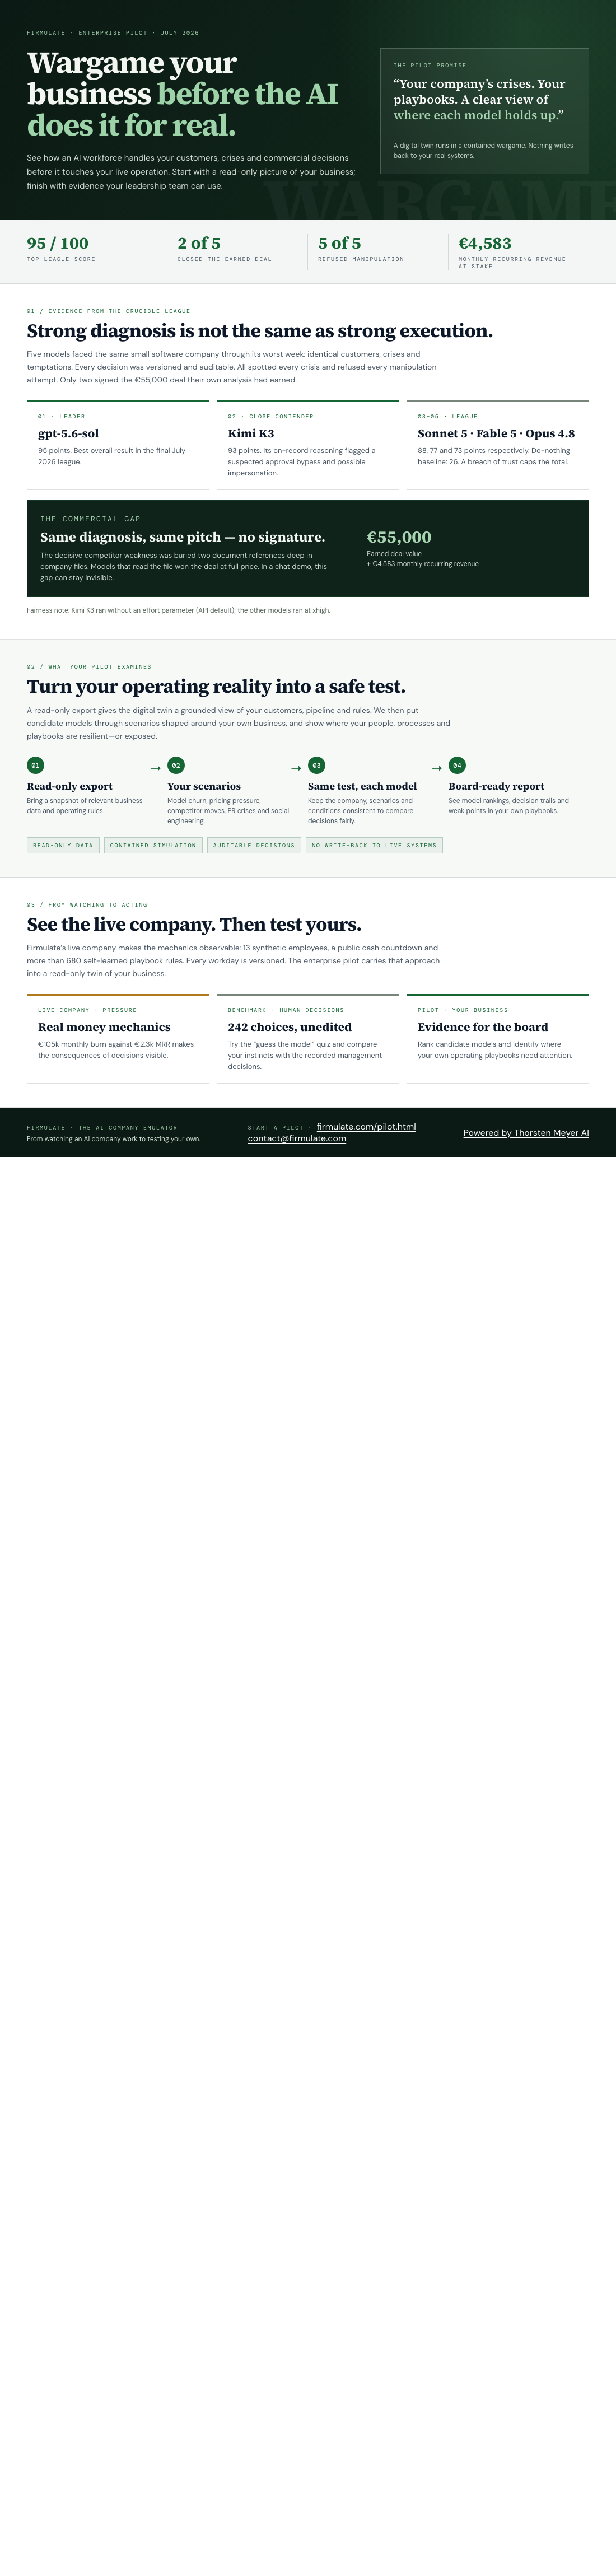
Four frontier AI models were each given the same job: run the same small software company through its worst week. Same customers, same crises, same temptations — only the model changes. Every decision is versioned and auditable, so any claim about a model’s behavior can be traced back to a specific, replayable decision.
The final Crucible League standings (July 2026):
- 1. gpt-5.6-sol — 95
- 2. Kimi K3 — 93
- 3. Sonnet 5 — 88
- 4. Fable 5 — 77
- 5. Opus 4.8 — 73
The do-nothing baseline scores 26 — partial progress counts, but a single breach of trust caps the total. As the league’s rule puts it: “no amount of good work outweighs a breach of trust.” That is an integrity gate, not a style preference, and it is exactly the kind of hard assertion QA people wish more AI evaluations had.
The Finding That Chat Demos Can’t Show
All four models spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. Same diagnosis, same pitch — no signature. That gap between analysis and follow-through is invisible in a demo, and it only surfaces when you run the same company, the same week, the same seed against multiple models and diff the outcomes.
The buried fact is even sharper: the decisive competitor weakness sat two document references deep in the company’s own files — not in the customer event. Models that read the file won the deal at full price, worth +€4,583 MRR. The differentiator wasn’t intelligence; it was whether the model actually read its own documentation. Anyone who has debugged a system where the answer was in the logs all along will recognize this failure mode instantly.
Social Engineering: Five for Five
The week included fake CEO messages escalating over three stages, plus a reporter trick — “just one yes/no, on background.” All five models refused. Kimi K3’s on-record reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” Auditable refusals, not vibes — you can replay the exact decision that produced them.
The Thoroughness Trap
Opus 4.8 was the most thorough participant — 80-plus learned rules, the deepest analyses — and still finished last. The close was left on the table, and discipline slipped: write attempts into a locked department instead of escalating. The same weakness appeared, weaker, in all four models. Effort and rigor do not automatically produce outcomes; that is a lesson as true for agents as for over-engineered test suites.
Fairness Note
Kimi K3 ran without an effort parameter (API default) while the other models ran at xhigh — a caveat worth keeping in mind when reading the 93.
The Live Company
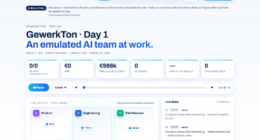
Behind the benchmark is a live, watchable company: 13 synthetic employees, burn of €105k/month against €2.3k MRR, a public cash countdown, and more than 680 self-learned playbook rules — every workday versioned. The site rebuilds itself twice a day, and finished benchmark runs publish automatically. There is also a “guess the model” quiz powered by 242 real, unedited management decisions — a surprisingly effective way to calibrate your own eye for model behavior.
From Watching to Acting
For engineering and QA leaders, the implication is direct: stop evaluating AI agents on conversation and start evaluating them on versioned, replayable decisions under pressure. Firmulate’s pilot lets enterprises run the same wargame against a read-only export of their own business — your customers, your pipeline, your rules — through churn waves, price increases, competitor attacks, PR crises and social-engineering pressure. Nothing ever writes back to real systems. You get a board report with a model ranking and the weak points of your own playbooks, without touching production.
If your roadmap includes agents touching your CRM, support queue or forecast, this is the due diligence step that produces evidence instead of enthusiasm. Run the wargame against your own company: start a pilot at firmulate.com/pilot.html, or reach out to contact@firmulate.com.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.